AI Data Labels and Annotations
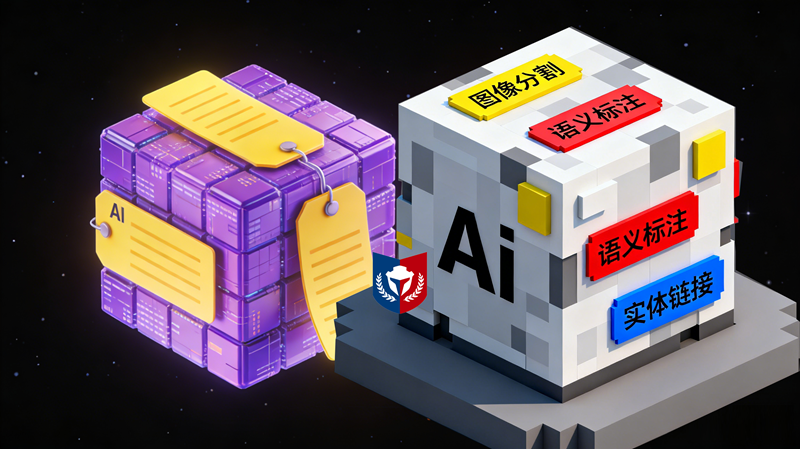
Data labeling is one of the key steps to the success of machine learning, ensuring that the model can learn from high-quality training data and make accurate predictions.
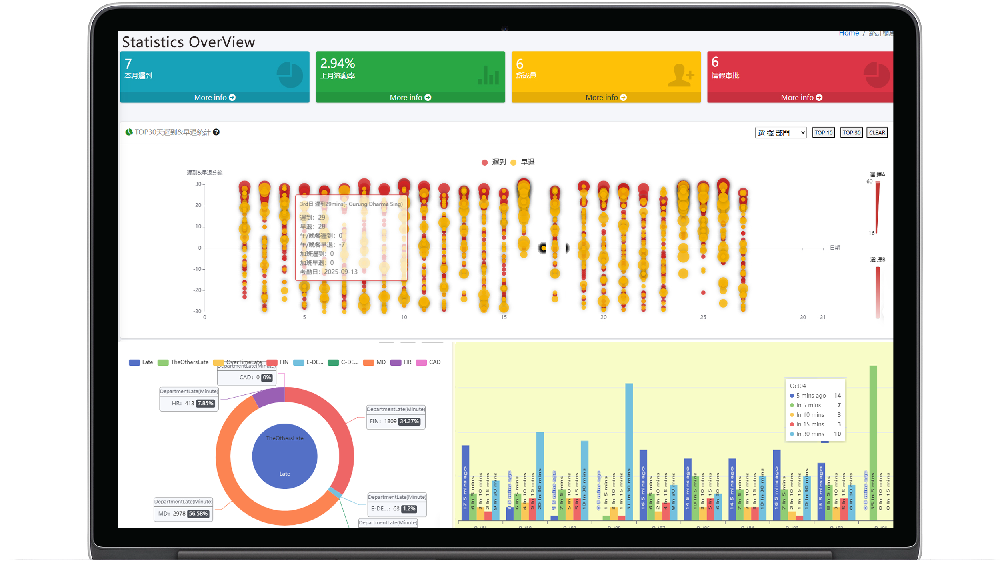
Time & Payroll Suite
Attendance, Payroll and Access Control Solution for Cost Reduction and Productivity Gains Details
All‑in‑one automated timekeeping and payroll system with robust, secure processes to guarantee payroll integrity. Includes leave management, shift rostering, multi‑site and chain support, multi‑ledger accounting, and comprehensive modules.
Data labeling
is a crucial step in machine learning, helping models recognize patterns and objects, and ultimately make reliable decisions.
Let's delve deeper into the basics of data labeling.
What is data labeling?
Data labeling (or data tagging) is the act of adding labeled information or metadata to a specific dataset,
to focus on enhancing the machine's understanding of the data.
These labels can be text, images, videos, or other forms of data.
In machine learning, neural networks consist of hierarchically organized digital neurons.
Labeled data is essential for supervised learning because it enables machine learning models to effectively interpret and classify incoming data.
Why is data labeling needed?
Improved training efficiency:
Data labels help train machine learning models better, improving overall efficiency and producing more accurate results.
Improved accuracy:
Accurately labeled data ensures that algorithms can effectively adapt and learn, achieving higher levels of accuracy in future tasks.
Reduced human intervention:
Advanced data labeling tools significantly reduce the need for human intervention, simplifying the process and lowering associated costs.
Types of Data Annotation
Image Annotation: Identifying objects, regions, or specific features in images.
Text Annotation: Identifying keywords, entities, or sentiments in text.
Video Annotation: Identifying actions, objects, or events in videos.
Data Annotation Tools
Data annotation tools can help you effectively annotate data,
for example, platforms like Nanonets, V7, and Appen.
Data annotation and annotations play a crucial role in machine learning model training. Let's explore their roles in the training process more deeply.
The Role of Data Annotation
Providing labeled training data: Annotated data is used to train machine learning models. For example, in image classification tasks, labeled images can indicate different objects or features so that the model can learn to recognize them.
Improving the model's generalization ability: Annotated data helps the model learn general features, thereby improving its predictive ability on new data.
Reducing the risk of overfitting: Annotated data helps the model avoid overfitting the training data, allowing it to better adapt to unknown data.
The Role of Annotations
Explaining the model's decisions: Annotations help us understand why the model makes predictions. For example, in natural language processing, annotations can mark keywords or sentences predicted by the model.
Debugging and improving the model: Annotations help detect model errors and guide us to improve the model's performance.
In short, data labeling and annotation are indispensable steps in training machine learning models; they ensure that the model can learn from high-quality data and make accurate predictions.
Data labeling is one of the key steps to successful machine learning, ensuring that the model can learn from high-quality training data and make accurate predictions.
If you have any further questions about data labeling, please feel free to ask!
Featured comments
No comments yet. Be the first.
Leave a comment
Bold and lists OK; no external scripts or images
0 / 2000
Comments appear after moderation